Saturday, 22 December 2018

Serialization inside

Why?
1. you want to store the state of your object, and shut down the jvm
come after 20 days and recreate the same object live in exactly same state.
Save where?
a. file
b.db
c. send to any other apps via network.

What is the alternative

1. you can create a REST request with all your data translated as json, send it to other party.
2. use ORM likr hibernation to store the state of your object in db.
Lets come back...
So make object state storable, java told if you want java to store the state of your object then tell the java same by implementing "serializable" interface and java will perform the serialization and deserialization algorithm for your object, if you use
objet.writeObject() and object.readObject().
what is algorithm (in short) during serialization
upon, obj.writeObject()jvm will
1. store the description of your serializable class, like its name, its serialversionUid,package name, what are fields, number of fields, type of fields
2. Same for its parents and its parents and on.
3. then it will store the the actual value of its top class parents class variable.
4. then come down to child, and child and store its variables actual value.
5. if during variables value assignment, if jvm find that variables is type of some user defined class(which implements serializable or not).
6. then process 1-2 repeats of storing that class definition, like its uid, number of variables, tupe of variables, up its parents hirarchhy, and the assign and store all the actual values.
7. then covert in to byte[] , write to file, db etc.

IMPORTANCE OF SERIALVERSIONUID

The idea of having serialVersionUID, it to force an update in client/de-serialization class and tell him, look, we updated our serializing class, if you want to use our new serialized object, you must update your de-serializing class as well.

How developer does it ?:

While modifying the new serializing class, he also changes the serialVersionUID manully.

Use case-1:

Code serialized the Object with uid = 10L

Client has a class with uid=10, which deserilised it , works fine both object's uid and deserilizing class's uid matches.

Use case-2:

Server has serialized few object on 1st Jan in DB with uid=10 and on 1st Feb server modified the code by adding a new field say "address" and removed old field "name" and changed uid=20  and client after 1 month, still has old class with uid=10.

then client will be able to de-serialized all the object which was stored during 1st Jan, but when it tries to de-serialized new object which were created after 1st Feb(with uid=20).

it will throw InvalidClassException, during de-serialized.

Why ?
Because if client doesn't update its de-serializing class, then it will not be able to recreate, new properties like address and will not find "name" value.
Hence after de-serialized the object will have name=null and adress will not at all be there.

Hence there is inconsistent, of object state and all purpose of saving/trasfering the state of object it lost/not achieved.

Wednesday, 19 December 2018

Why static code cant have instance reference

Because static code are loaded in when class gets loaded via classloader and at that time, no instance of that class would have got created...
hence compiler finds the issue and complains.

Immutability

How to break immutability if class
1. has private fields
2. no setter method
3. proper constructor for obj creation.
but failed to.mark the class as final.

then effectively, you created your immutable class and told everyone that, use my object, wherever for all immutable features, like storing immutable object as key

but since its nit final, any class
1. can extend it.
2. provide a setter functionality for its own private varible ,hence not immutable.
3. type cast this immutable object to mutable type reference.

and start passing where you had passed your immutable object , breaking your promises.

so.mark it final, so that no one can extend it.

Static Vs Dynamic Binding


similarly
binding happens for static method, they will be binded to a class they belongs.


Friday, 14 December 2018

Recursion vs Iterative


Recursion :

Advantage :
Best suited for tree structure sort of problem, like trees , makes code look less complex.

Disadvantage :
1. Use lots of Stack , as each stack call, will have its own variable
2. Difficulties during debugging


Iteration :
Just reverse advantage and disadvantages :)

Thursday, 13 December 2018

JSON parsing sample


Java Script Object Notation.


Using the org.json library:
JSONObject obj = new JSONObject("{interests : [{interestKey:Dogs}, {interestKey:Cats}]}");

List<String> list = new ArrayList<String>();
JSONArray array = obj.getJSONArray("interests");
for(int i = 0 ; i < array.length() ; i++){
    list.add(array.getJSONObject(i).getString("interestKey"));
}

Daemon threads


thread.setDaemon(true)

If you don't do that, and you run some infinite loop in your thread's run(), that code will keep on executing even after your main application finishes, i.e. it will never let JVM shutdown.


Generally used for helping the main app, as long as main app runs , like GC.


Quick summary : Dead lock and race condition


DEADLOCK:

When :
two threads try to acquire series(two of more) lock in an inconsequential order.

i.e
T1 --> Object1 lock --> sleep for some time(does time consuming tasks) --> Object2 lock.
T2 --> Object2 lock --> sleep for some time(does time consuming tasks)  -> Object1 lock

the problem here is , while both threads are able to acquire some object lock and tries to acquire lock of another object, while still holding the previous object lock.


resolution :
Make sure in your code, all threads acquire the locks in a sequential manner.


T1 --> Object-1 lock --> sleep for some time(does time consuming tasks) --> Object-2
T2 --> Object-1 lock --> sleep for some time(does time consuming tasks) --> Object-2

this way if thread-1 acquire the Object-1 lock, no other threads will be able to acquire the object-1 lock.

and once thread-1 finishes doing his task, may be by acquiring object-1,Object-2 lock, it release all the locks for other threads.


RACE 

Basically, its to do with bad programming of creating a sequence of code, which are not thread safe.
ex:
out of 5 lines of code, 3 lines of code is executed by one thread and cpu scheduler, takes out your thread and allows other thread to run, allowing to change the state of object, then your previous thread come back and tries to read from line 4, assuming the state is unchanged as his last read but thread 2 has changed the state..

example :

One back account, two ATM card holder,
Check then act concept(Check the balance  and then withdraw)


Why String is Immutable


So that , by changing the Object reference , doesn't actually alter the desired behavior , like above.

In above example:
While storing a Key, we passed a String reference variable, which was pointing to "hk" during insertion, so the contract with retriver was make, that you mst use this key to retrieve the object, but suppose after 1 year, one simple line is added after insertion, S1.uppercase(),

If String was mutable, the key in HashCode, would have got changed.

If Java changed the actual value/key of hashtable, while user changes the reference, then if some client does hm.get("hk"), it would give Null, hence undesirable behavior.

Similar issues arises if you use String as some URL, leads to security concerns for your application.

Credits : https://www.youtube.com/watch?v=ZMfMMbEzKE4


Open for extension and closed for modification


 For example, the Collections.sort method knows how to sort everything that implements the Comparable interface. This method is not limited to sorting just integers or just strings — it is not limited to any specific type. If you have a collection of objects that implement the Comparable interface, then you can sort it using the Collections.sort method. The sorting algorithm will work as it was designed, so we can say that it is closed to modification, but the sorting criteria will vary depending on the compareTo method implementation


The alogorithm is closed for modification, its merge sort used in Collection.sort(List<Comparable objects>).

But how your compare your two objects after implementing Comparable and overriding " int compareTo(Object o)" , is open for extension.

Wednesday, 12 December 2018

Monday, 10 December 2018

REST API and http/https


REST call :

Transfer the Representation of resource in a current state.

Always choose/identify the resource first.


Implementation: 
1. Jersey
2. Bboss
3.Java JAX-WS

http://15.154.119.102:8080/nfvd/instance/artifact/query/path?id=26379b81-b522-49a2-b0de-e7ea77f3905f&expression=ORGANIZATION:GENERIC>TENANT:GENERIC

Class level @path: "/instance/artifact";


PathaParam: to reach a specific resource /city/population, /city/weather/

QueryParam: to filter out more of that path, like /city/?name=Bangalore.

There are twi way of design, in generation, you must design in a such way that your path/URL, doesn't change much.


HTTPS :

Credits :
https://www.youtube.com/watch?v=iQsKdtjwtYI


Wednesday, 5 December 2018

Process vs Threads


Process are heavy during context switching, mainly because of "Virtual to physical address translation" in processes which is not required in threads as they share same memory address space


Wednesday, 28 November 2018

Garbage collector process in java

Courtesy : https://www.youtube.com/watch?v=UnaNQgzw4zY


Eden:
All new object

S1: one Eden is full, Minor CG , unrefrenced Eden objected are marked and sweep and later moved(compacted to S1)

So after one minor CG(Eden and S2 will be free)

S2: now when again eden is full, Minor GC kicks in this time on Eden and S1 space,
Unreference object from Eden and S1 are marked and


Serials: STOPS the work
Concurrent: Stops App only for mark step, doenst wait for Old generation to be full, after marking, it runs along with app, performing sweep and compact task

Parallel: uses multiple GC threads, but its stop the world/App, runs only after % of Old generation is full, it stops the app, but uses multple GC,

Best: CMS


ArraLIst Vs Linked List


The difference can be seen in underlying implementation and below time complexity.

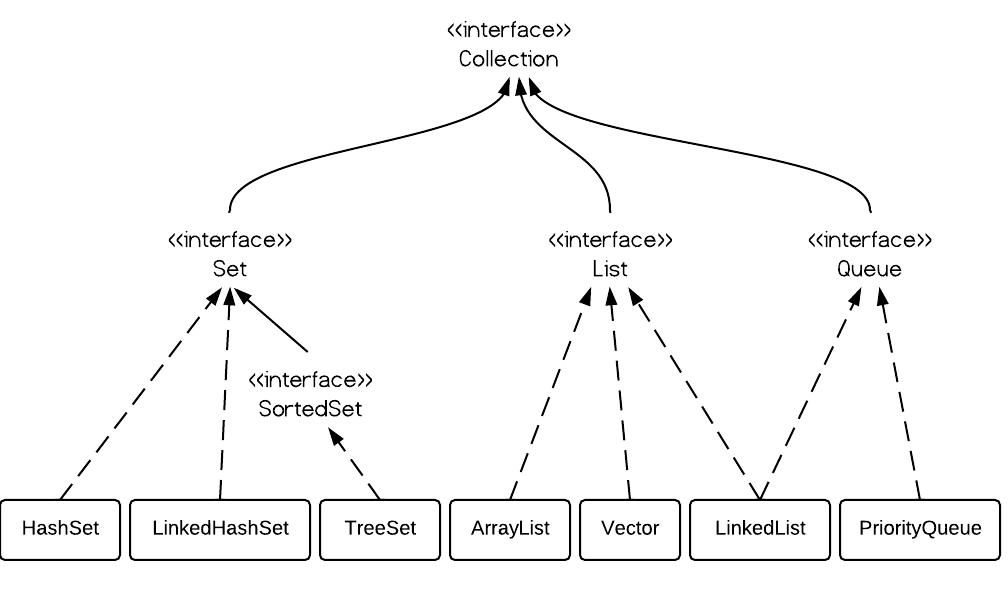
LinkedList also implements Queue, hence gets the properties of Queues, (FIFO),
main difference is in traversal, in LinkedList you have to traverse link by link, hence get operation is
of O(n).

The time complexity comparison is as follows: 
arraylist-vs-linkedlist-complexity


Thursday, 6 September 2018

Mockito : Mock a method level local object


The method to be tested, which internally creates a local Object of MyOtherClass, which can not be set/mocked via Constructor

public class MyClass {
    public someReturn myMethod(){
        MyOtherClass otherClassObject = new MyOtherClass();
        boolean retBool = otherClassObject.otherClassMethod();
        if(retBool){
            // do something
        }
    }
}


So use power Mock, to say, whenever a new object with default contructor is called, use above object,
and you can add any other propery for your mocked object


@RunWith(PowerMockRunner.class)
@PrepareForTest(MyClass.class)  //tells powerMock we will modify MyClass to intercept calls to new somewhere inside it
public class MyClassTest{
    @Test
    public void test(){
          MyOtherClass myMockOtherClass = createMock(MyOtherClass.class);
          //this will intercept calls to "new MyOtherClass()" in MyClass
          whenNew( MyOtherClass.class).withNoArguments().thenReturn( myMockOtherClass ) );          when(myMockOtherClass.otherClassMethod()).thenReturn(true);


   }
Ref : https://stackoverflow.com/questions/29398283/mocking-a-local-object-inside-a-method-of-sut-using-mockito-or-powermocktio?rq=1

Saturday, 25 August 2018

Queue implementation in java


Queue --> Dequeue --> LinkedList

Queue : Only add() from tail and remove() from head (FIFO obviously)


Dequeue: add() and remove() from both the sides methods like addFirst(10),addLast(10),removeFirst(),removeLast().


Notes on LinkedList

1. it maintained all node as 

Node<E> Object attributes{
E item;
Node next;
Node previous;
}

So if you want to implement you own queue/LinkedList,  you should have similars fields

2. remove and add, increase the size field of
Class LinkedList {

int size =0;
Node first/head;
Node last/tail;

}

add(item) {
added to tail, but if head is also null, then head and tail both should point to same.


Sunday, 19 August 2018

Why to override hasCode() and equals() together ?


Lets say your class:

Public Employee {

int empId;

Override only equals()

public boolean equals(Employee other) {

if(this.empId == other.empId) { return true}
else { return false;}

}

You will not face any issues, while using your class , till you start storing your class's object in to any hash implemented collection like HashMap,HashSet etc.


Lets say you want to store you Employee objects in to HashMap.

First lets understand, how HasMap stores the data in it.


Its a Linked List of Linked List
All indexes 0-15 are like linked buckets, then in side each bucket there is another linked list of Map.Entry, for all collision Object with same Bucket Id.


Quick logic of HashMap.put(Key,value)

1.  It first invokes the Key.HashCode() --> say 2001
2. Then tries to find the BucketId/IndexId where it has to place this object --> say divide by n  = 2
3. If next put also result in same bucketId, then that new node will be added to next node of that bucket, line above picture, key4 and key5


Coming back to question again.

Lets your class has only overridden the equals, then each time "new Employee(10)" will produce new Hashcode(Object native memory address , integer representation).

and when you do hashMap.get(new Employee(10), you will never find your object in the map, even though you had added it.

Hence you should provide you unique was of generating hashcode for your class,


Question -2

if you override only HashCode() but not equals

Then suppose your --> new Employee(10) and new Employee(11) goes in to same bucket, then, when you do hasMap.get(new Employee(10)), it will find the bucket, but in the bucket how would find exact object,

becaue inside the bucket each node's "searchedKey.equals(BucketNextkey)" will be invoked, and default implementation of Object's class equal is ==, it check if reference is same,

hence you will never find your Object inside map,even if you has put it.